Machine Learning
Master 2 SMSDS · Paris Cité University & Sorbonne UniversitySyllabus
Objectives
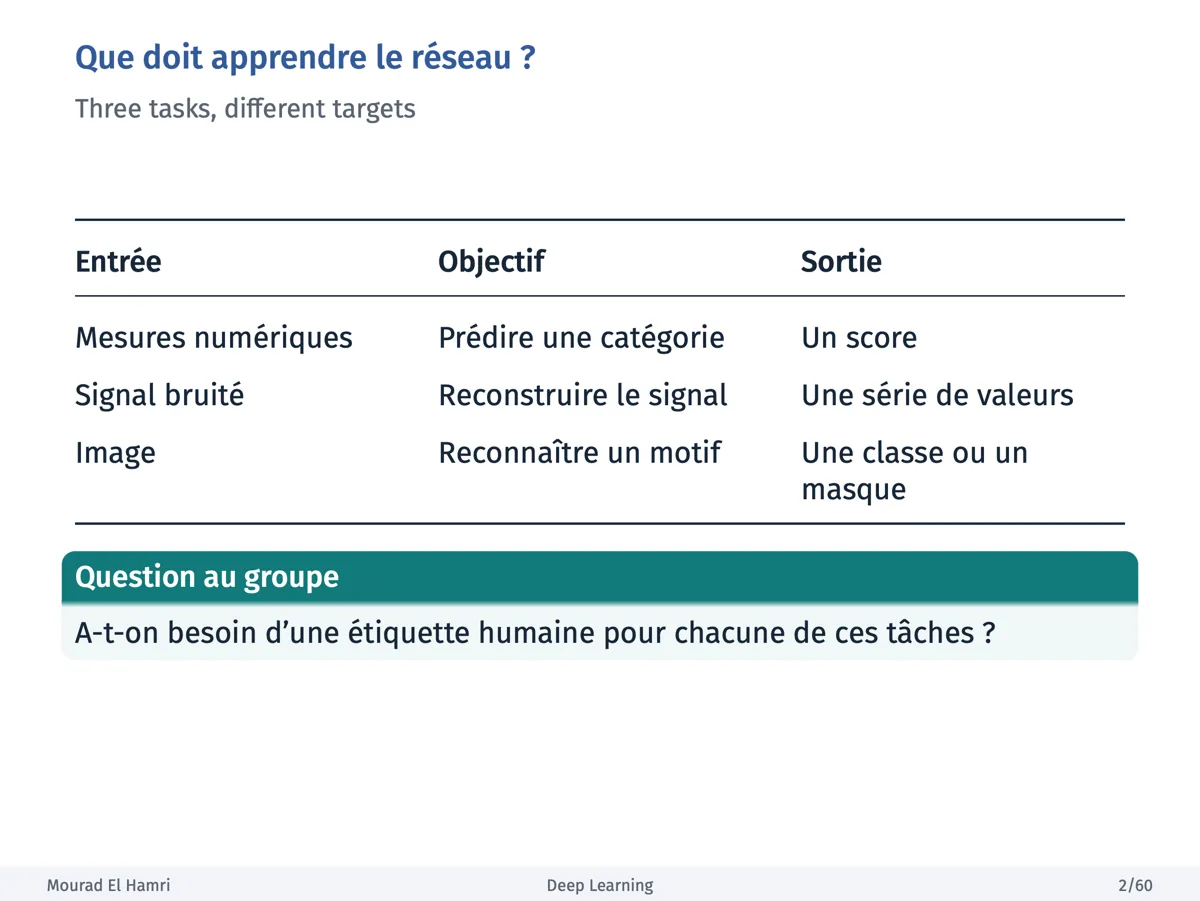
Understand the statistical foundations of supervised and unsupervised learning, and implement the main classification and clustering methods in Python or R, with rigorous model evaluation and selection.
Prerequisites
Probability and statistics, linear algebra, and basic programming in Python or R.
Practice
Hands-on exercises in Python or R on real datasets, applying both supervised and unsupervised learning methods.
Outline
- Introduction: artificial intelligence, symbolic artificial intelligence and machine learning
- Foundations of learning: empirical risk minimization, overfitting, the No-Free-Lunch theorem, the bias–complexity trade-off, structural risk minimization, regularized empirical risk minimization, validation and cross-validation
- Supervised classification: k-nearest neighbours as a first algorithm, and evaluation metrics such as accuracy, the confusion matrix, precision, recall, the F1 score, the receiver operating characteristic curve and the area under the curve, the Brier score and Cohen’s kappa
- Generative methods: the Bayes classifier, naive Bayes and Gaussian naive Bayes, linear and quadratic discriminant analysis, Gaussian mixture models
- Discriminative methods: logistic regression, decision trees and support vector machines
- Unsupervised learning: k-means, hierarchical clustering, Gaussian mixture models, DBSCAN and spectral clustering
Slides